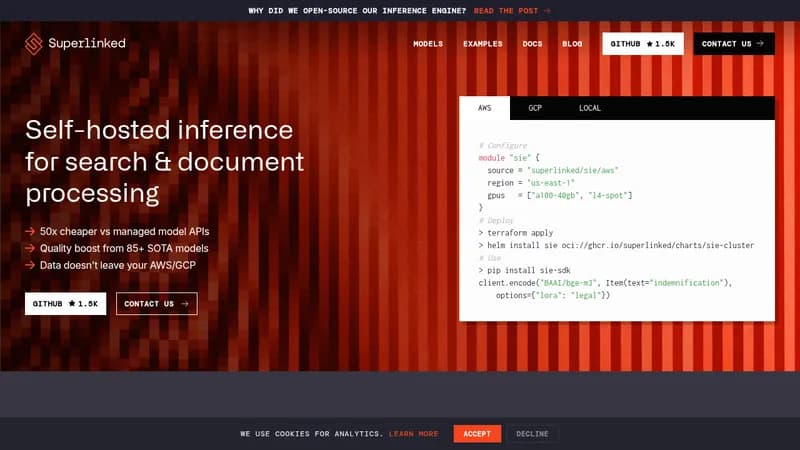
Superlinked Inference Engine (SIE) is a self-hosted inference server for search and document processing workloads. It provides a unified cluster to run embeddings, reranking, and extraction models while keeping data within your own cloud (AWS/GCP). SIE offers 85+ state-of-the-art open-source models, SDKs in Python and Node.js, and integrations with vector databases like Chroma, LanceDB, Qdrant, and Weaviate. It is designed to reduce API costs by up to 50x compared to managed model APIs and is licensed under Apache 2.0.
Key Features
- Cost savings: Pay for your own GPUs instead of per-token API pricing, with spot instance support.
- Model variety: Access 85+ models for embedding, reranking, extraction, and multi-modal tasks.
- Data privacy: Inference runs entirely within your cloud infrastructure; SOC2 Type2 certified.
- Deployment flexibility: Deploy via Terraform modules for AWS/GCP, run locally with Docker, or manage with Helm charts.
Who It's For
Developers, data scientists, and AI engineers building search systems, RAG pipelines, or document processing applications that require low-latency, cost-efficient, and private AI inference.
Key Benefits
- Up to 50x cheaper than managed model APIs
- 85+ state-of-the-art open-source models available
- 100% data control; inference never leaves your cloud
- Apache 2.0 licensed and open-source