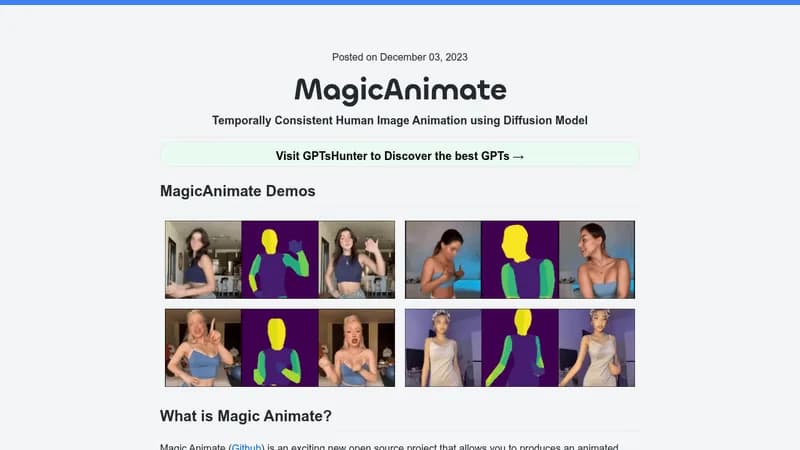
MagicAnimate is an open-source diffusion-based framework for human image animation. It produces temporally consistent animated videos from a single reference image and a motion video. The tool maintains high temporal consistency, faithfully preserves the reference image, and enhances animation fidelity. It supports cross-ID animations and can animate unseen domains such as oil paintings and movie characters. MagicAnimate integrates with text-to-image diffusion models like DALLE3 to bring text-prompted images to life. Built by Show Lab at National University of Singapore and Bytedance, it offers the highest consistency among current dance video solutions.
Key Features
- Temporal Consistency: Maintains smooth motion across frames.
- Reference Image Preservation: Faithfully retains the appearance of the input image.
- Cross-ID Animation: Animate different identities with the same motion sequence.
- Domain Generalization: Works on anime, oil paintings, and movie characters.
- T2I Integration: Seamlessly works with models like DALLE3.
Use Cases
- Dance video generation from a single photo.
- Animating characters from various art styles.
- Creating motion sequences for virtual avatars.
Who It’s For
Researchers, developers, and AI artists interested in human animation and video generation.
Workflow
- Provide a reference image and a motion video (or OpenPose keypoints).
- The model generates an animated video maintaining the reference appearance.
- Optionally, use OpenPose to convert any video into motion data.
Requirements
- Python >= 3.8, CUDA >= 11.3, ffmpeg.
- Pretrained StableDiffusion V1.5 and MSE-finetuned VAE models.
- MagicAnimate checkpoints from HuggingFace.