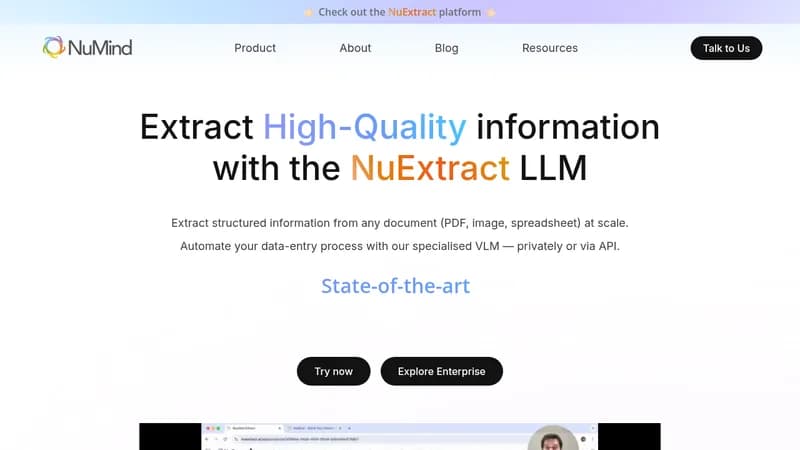
NuExtract is a specialized vision-language model (VLM) designed for extracting structured information from documents at scale. It processes PDFs, images, and spreadsheets to automate data-entry tasks, offering a low hallucination rate by explicitly indicating missing data with “I don’t know” responses.
Key Features
- Low hallucination rate with explicit missing-information handling
- Supports multiple document formats: PDF, images, spreadsheets
- Outperforms frontier LLMs/VLMs in extraction benchmarks
- Available as a SaaS API or private on-premise deployment
Use Cases
- Invoice, contract, and form parsing
- Email, resume, and spreadsheet extraction
- Industry-specific extraction for banking, insurance, healthcare, legal, logistics, manufacturing, public sector, defense, energy, HR, marketing, and real estate
Who It’s For
- Organizations needing to automate data entry from unstructured documents
- Teams requiring high-accuracy extraction with minimal hallucination
- Enterprises looking for private, self-hosted extraction solutions
Key Benefits
- Low hallucination rate with explicit "I don't know" capability
- Outperforms frontier LLMs/VLMs in extraction tasks
- Supports multiple document formats (PDF, images, spreadsheets)
- Private deployment option for sensitive data