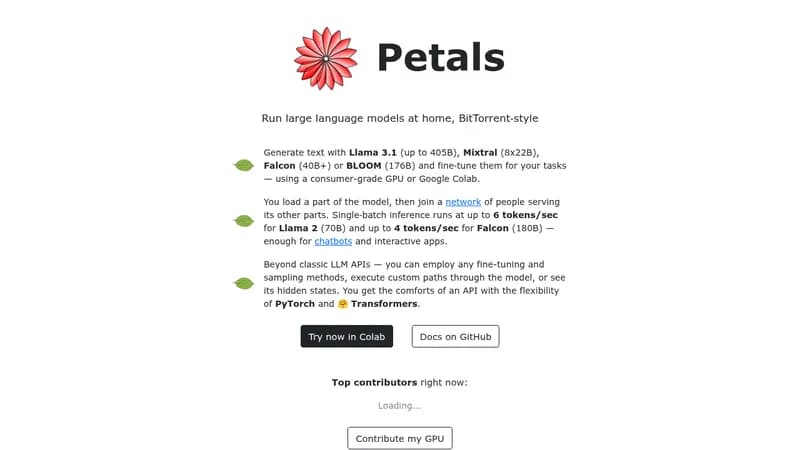
Petals is a decentralized platform for running large language models (LLMs) at home using a BitTorrent-style peer-to-peer network. It supports models like Llama 3.1 (up to 405B), Mixtral (8x22B), Falcon (40B+), and BLOOM (176B). Users load a part of the model and join a network of peers serving other parts, enabling inference and fine-tuning on consumer-grade GPUs or Google Colab. Single-batch inference reaches up to 6 tokens/sec for Llama 2 70B and up to 4 tokens/sec for Falcon 180B, sufficient for chatbots and interactive apps. Petals goes beyond standard LLM APIs by allowing custom fine-tuning, sampling methods, custom model paths, and access to hidden states, combining the ease of an API with the flexibility of PyTorch and Hugging Face Transformers. The project is part of the BigScience research workshop.
Key Benefits
- Runs large models on consumer-grade hardware
- Supports fine-tuning and custom sampling
- Flexible API with PyTorch and Transformers integration
- Decentralized network leverages idle GPUs