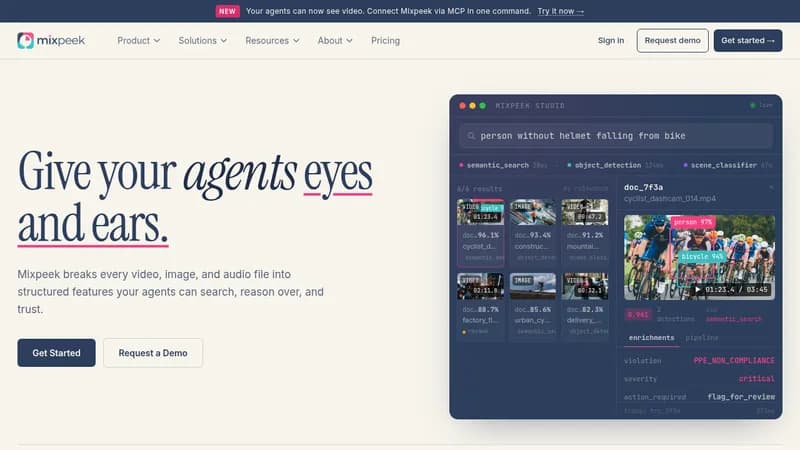
Mixpeek is a multimodal data warehouse that decomposes video, image, and audio files into structured, searchable features. It provides a complete system for ingestion, extraction, tiered storage, multi-stage retrieval, and audit trails, all behind a single set of primitives.
Key Features
- Feature Extractors: Turn every file into a hierarchy of typed features: faces, scenes, transcripts, logos, and fingerprints. Versioned pipelines with composable extractors.
- Multi-stage Retrievers: Compose search, filter, join, and rerank stages in one call with deterministic execution and full audit traces, typically under 100ms.
- Taxonomies & Ontologies: Encode domain knowledge as versioned reference collections enforced at query time, ingest time, or retroactively.
- Tiered Feature Store: Hot, warm, cold, and archive tiers that automatically manage storage based on access patterns, reducing costs by 60-80%.
- Clusters: Discover structure with 8 algorithms, auto-label with LLMs, and promote stable clusters to taxonomy nodes.
- Agent-ready: MCP server, LangChain retriever, OpenAI function calling, and REST API allow agents to reason over structured features with lineage.
Use Cases
- Talent search: Find faces across video libraries with exclusivity checks.
- IP & Copyright detection: Scan creative assets against protected face, logo, and audio databases.
- Visual taste recommendations: Scene-similarity ranked recommendations using reinforcement learning.
- Brand safety: Pre-publish content screening at bid-time speeds.
Who It’s For
Mixpeek is built for developers, media operations, and compliance teams in advertising, entertainment, e-commerce, and education who need to query unstructured media at scale.