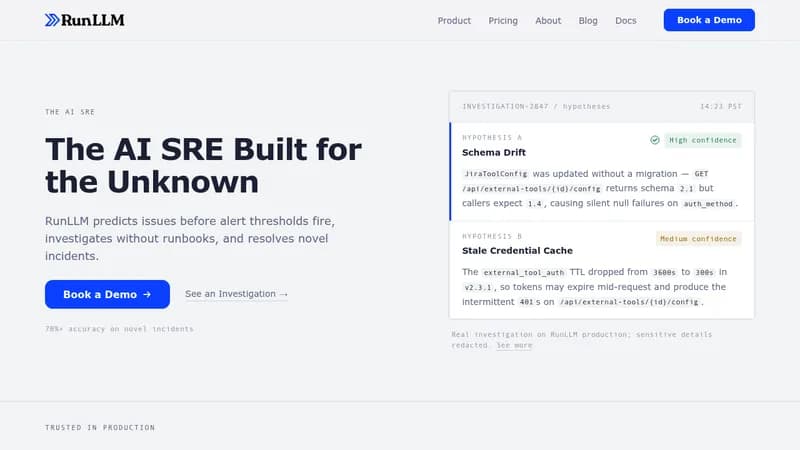
RunLLM is an AI Site Reliability Engineer (SRE) that predicts issues before alert thresholds fire, investigates without runbooks, and resolves novel incidents. It builds a context graph from observability data, codebase, CI/CD, docs, and dependencies to understand what normal looks like. It detects anomalies without threshold tuning and investigates multiple hypotheses simultaneously to deliver root cause analyses (RCAs) in minutes, even for incidents it has never seen before.
Key Features
- Proactive Detection: Custom anomaly detection models per data stream filter false positives and surface validated issues before customers notice.
- Autonomous Investigation: Evaluates multiple hypotheses (e.g., load spike, code change, memory leak) against the right data sources, eliminating the need for runbooks.
- Continuous Learning: Learns from every investigation to avoid repeating mistakes.
Use Cases
- Detecting and diagnosing novel production incidents that lack predefined runbooks.
- Identifying issues like schema drift, stale credential caches, or silent failures before alert thresholds trigger.
- Reducing manual toil for SRE teams by automating root cause analysis.
Who It's For
Site reliability engineers and platform teams managing complex, evolving infrastructure.
Key Benefits
- 70%+ accuracy on novel incidents without runbooks
- Proactive anomaly detection without threshold tuning
- Autonomous investigation of multiple hypotheses simultaneously
- Learns from every investigation to avoid repeated mistakes