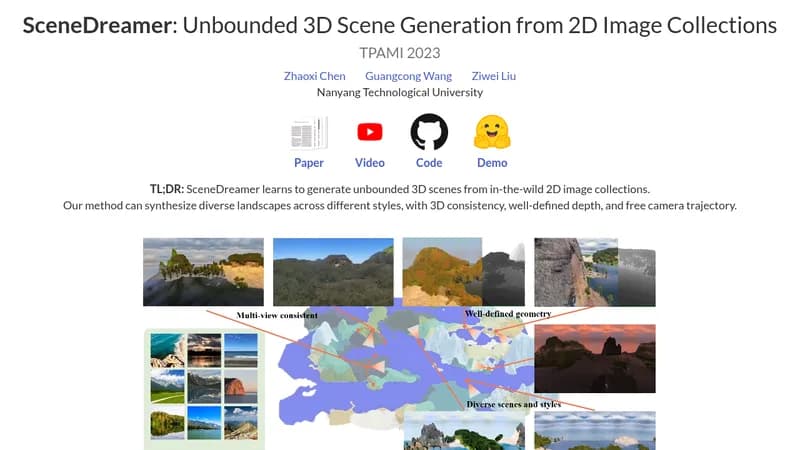
SceneDreamer is an unconditional generative model for unbounded 3D scenes, trained solely on 2D image collections without 3D annotations. It synthesizes large-scale 3D landscapes from random noise, enabling free camera movement with 3D consistency. The framework uses a bird's-eye-view (BEV) representation consisting of a height field and a semantic field, derived from simplex noise. A generative neural hash grid parameterizes the latent space based on 3D positions and scene semantics. A neural volumetric renderer, trained adversarially on 2D images, produces photorealistic renderings. The model achieves state-of-the-art results in generating diverse, unbounded 3D worlds.
Key Benefits
- Trained only on 2D images, no 3D data needed
- Synthesizes large-scale 3D landscapes
- Produces 3D-consistent renderings with free camera control
- State-of-the-art performance on unbounded 3D scene generation