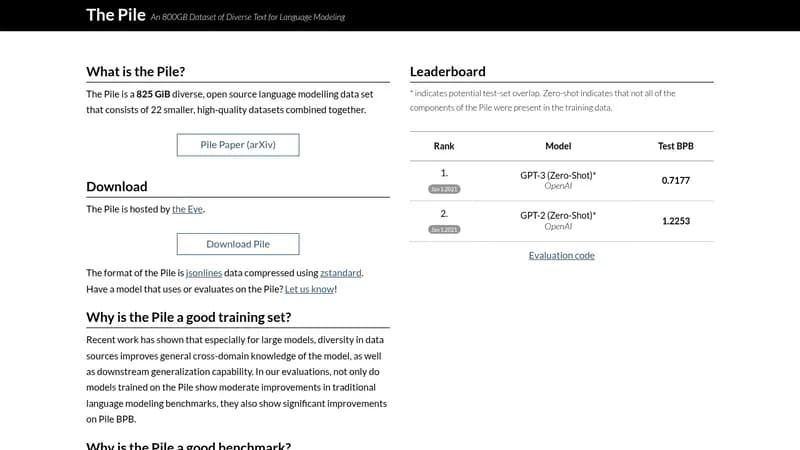
The Pile is a 825 GiB diverse, open-source language modeling dataset composed of 22 smaller, high-quality datasets. It is designed to improve cross-domain knowledge and downstream generalization in large language models. The dataset is provided in jsonlines format compressed with zstandard and is freely available for download. The Pile also serves as a robust benchmark for evaluating language models across multiple domains including books, code, web pages, chat logs, and academic papers. A leaderboard tracks model performance on Pile bits per byte (BPB).
Key Benefits
- Diverse data sources improve cross-domain knowledge
- Improves downstream generalization capability
- Serves as a robust benchmark for language models