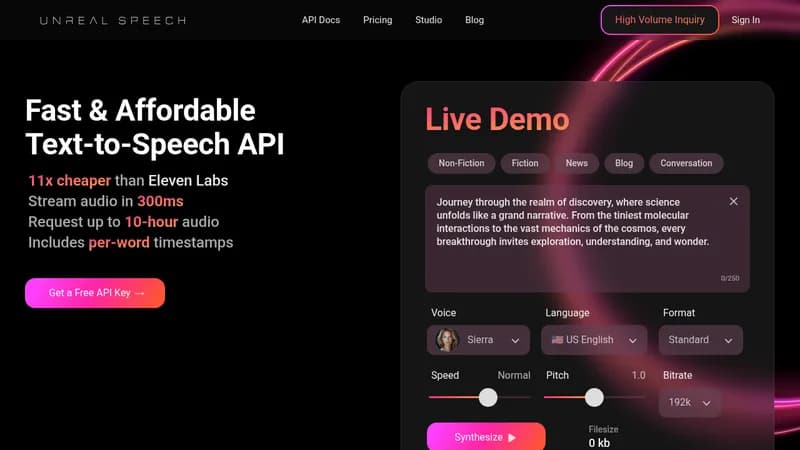
Unreal Speech is a text-to-speech API designed for speed and cost efficiency. It enables developers to integrate speech synthesis into applications with low latency (0.3s for short streams) and support for long-form audio (up to 10 hours per request). The API offers multiple endpoints for different use cases: /stream for instant audio up to 1,000 characters, /speech for synchronous synthesis up to 3,000 characters, /synthesisTasks for asynchronous long-form generation up to 500,000 characters, and /streamWithTimestamps for real-time word-level timestamps via WebSocket.
Key Features
- Low latency: Stream audio in 300ms.
- High volume: Request up to 10-hour audio in 15 minutes.
- Per-word timestamps: Highlight words in sync with speech.
- Multiple voices and languages: 48 voices across 8 languages (US English, UK English, Mandarin Chinese, Hindi, Spanish, Portuguese, Japanese, French, Italian).
- Flexible pricing: Pay-as-you-go with volume discounts; enterprise plan includes 625M characters per month.
Use Cases
- Real-time voice applications (e.g., chatbots, interactive assistants).
- Long-form audio generation (e.g., audiobooks, podcasts, narration).
- Word-by-word highlighting for reading tools or language learning.
Who It’s For
Developers and businesses needing scalable, cost-effective text-to-speech for applications, from small projects to high-volume production systems.