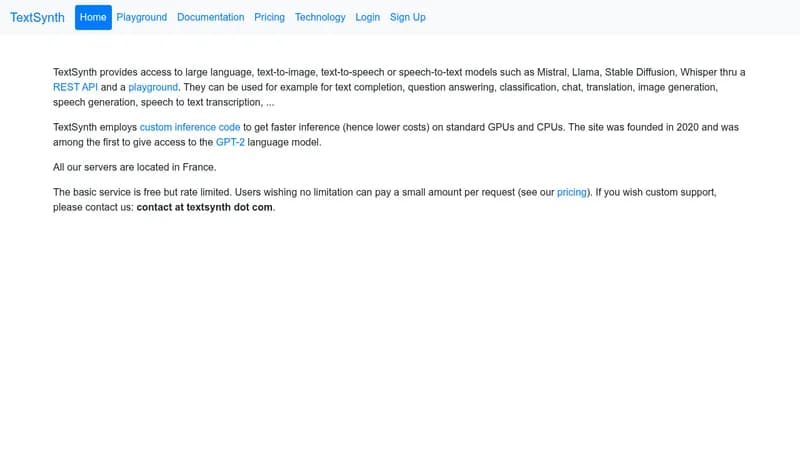
TextSynth is a service that provides access to large language models (e.g., Mistral, Llama), text-to-image models (e.g., Stable Diffusion), and speech models (e.g., Whisper) through a REST API and a playground. It enables use cases such as text completion, question answering, classification, chat, translation, image generation, speech generation, and speech-to-text transcription. TextSynth employs custom inference code to achieve faster inference speeds on standard GPUs and CPUs, reducing costs. Founded in 2020, the service operates servers located in France. The basic tier is free but rate-limited; users can opt for pay-per-request pricing to remove limitations.
Key Features
- REST API and playground for accessing multiple AI models
- Custom inference code for faster performance on standard hardware
- Support for language, image, and speech models
Use Cases
- Text completion and generation
- Image generation from text prompts
- Speech transcription and generation
Who It’s For
- Developers and researchers needing API access to state-of-the-art models