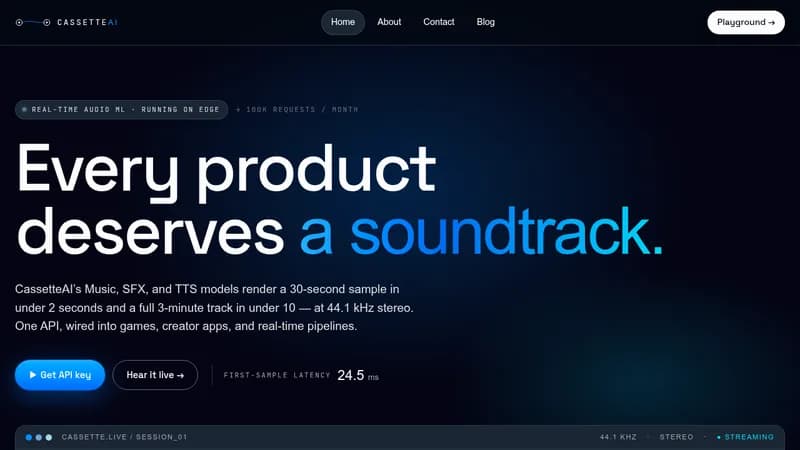
CassetteAI is a real-time generative audio API providing music, sound effects, and text-to-speech models optimized for edge inference. It enables developers to integrate high-quality, low-latency audio generation into games, creator applications, and real-time pipelines through a single unified API.
Music Generation
Generate full 1–4 minute tracks at 44.1 kHz stereo from text prompts describing mood, genre, or references. A 30-second sample renders in under 2 seconds; a complete 3-minute track finishes in under 10 seconds. Outputs include drums, bass, harmony, and lead layers.
Sound Effects
Create up to 30 seconds of loop-safe, per-frame re-rollable audio from descriptive prompts—e.g., "heavy door slamming in a cathedral"—with typical generation latency around 1 second.
Text-to-Speech (Coming Soon)
Streaming-first TTS with zero-shot voice cloning from a 10-second sample, emotion tags, and sub-second first phoneme.
API and Workflow
All models are accessed via fal.subscribe() using a single API key and consistent call shape. The API runs on edge hardware, delivering a first-sample latency as low as 26.6 ms. Output files are 44.1 kHz stereo WAVs.