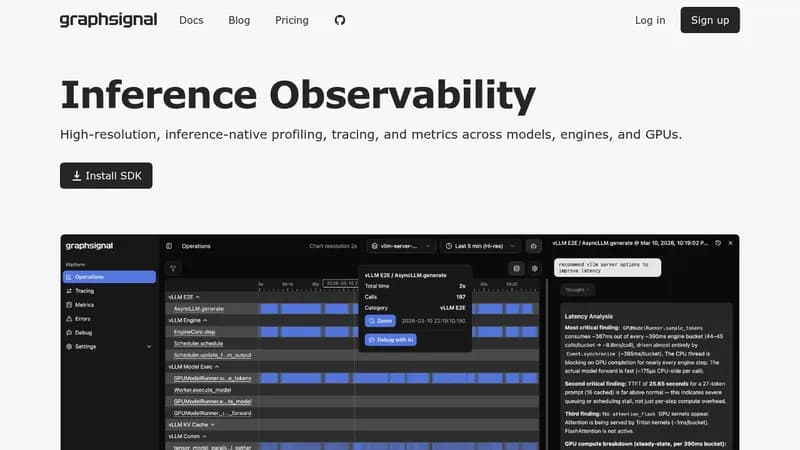
Graphsignal is an inference observability platform that provides high-resolution profiling, tracing, and metrics across models, engines, and GPUs. It is designed for AI teams deploying and optimizing inference workloads.
Key Features
- Inference profiling: Continuous, high-resolution profiling timelines exposing operation durations and resource utilization across inference workloads.
- LLM tracing: Generation tracing with per-step timing, token throughput, and latency breakdowns for major inference frameworks.
- System metrics: System-level metrics for inference engines and hardware (CPU, GPU, accelerators).
- Error monitoring: Monitors device-level failures, runtime exceptions, and inference errors.
- AI optimization: Inference telemetry for AI agents to identify bottlenecks and drive targeted improvements across the inference stack.
Supported Platforms
Graphsignal integrates with NVIDIA, PyTorch, Hugging Face, vLLM, and SGLang.
Key Benefits
- High-resolution inference profiling with operation durations and resource utilization
- LLM generation tracing with per-step timing and latency breakdowns
- System-level metrics for CPU, GPU, and accelerators
- Error monitoring for device-level and runtime failures