To pick the right AI model, use the cheapest tier that passes your task and save the flagship for hard, high-stakes work. Three questions decide the tier: how hard is the reasoning, how often will the task run, and what does a wrong answer cost?
Simple, frequent and low-stakes work goes to a budget model. Complex, rare and high-stakes work earns the flagship. Everything in between starts on a mid-tier model.
What you'll get from routing tasks by tier
You get the same workloads at a lower monthly bill, priced on API rates checked October 21, 2026. Here are two workloads, before and after routing.
| Workload | Before | After | Gap |
|---|---|---|---|
| Short factual answers: 60M input + 30M output tokens a month | Claude Opus 5.5: $840 | Claude Haiku 5.5 or GPT-6 Luna: $21 | 40x |
| Support email drafts: 12M input + 9M output tokens a month | Claude Opus 5.5: $228 | Claude Sonnet 5.5: $114 | 2x |
The first workload is 10,000 short questions a day at about 200 input and 100 output tokens each. The second is 1,000 emails a day at about 400 input and 300 output tokens each. Both assume a 30-day month.
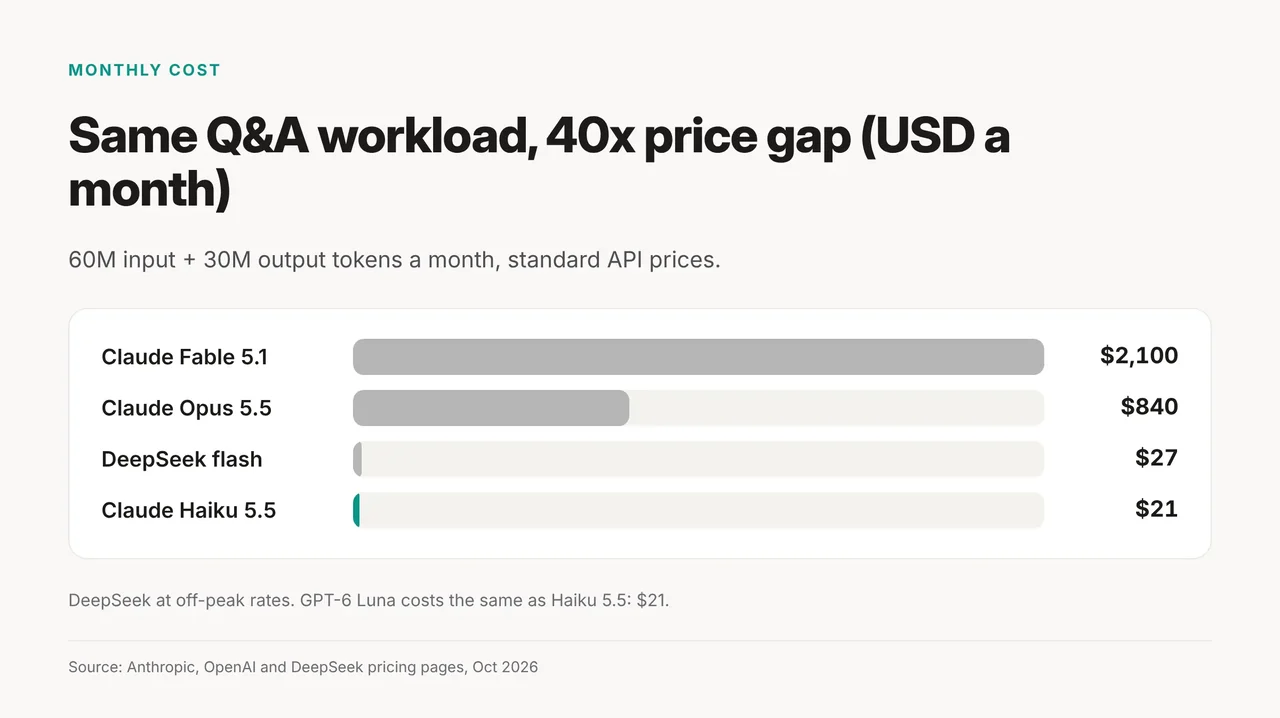
Switching the Q&A workload from Opus 5.5 to Haiku 5.5 saves $819 a month. Switching email drafts to Sonnet 5.5 saves $114. These figures are prices, not quality: the cheaper tier still has to pass your own test first.
Which tier fits which task?
The three questions map each task to one of three tiers. Answer them in order and stop at the first tier that fits.
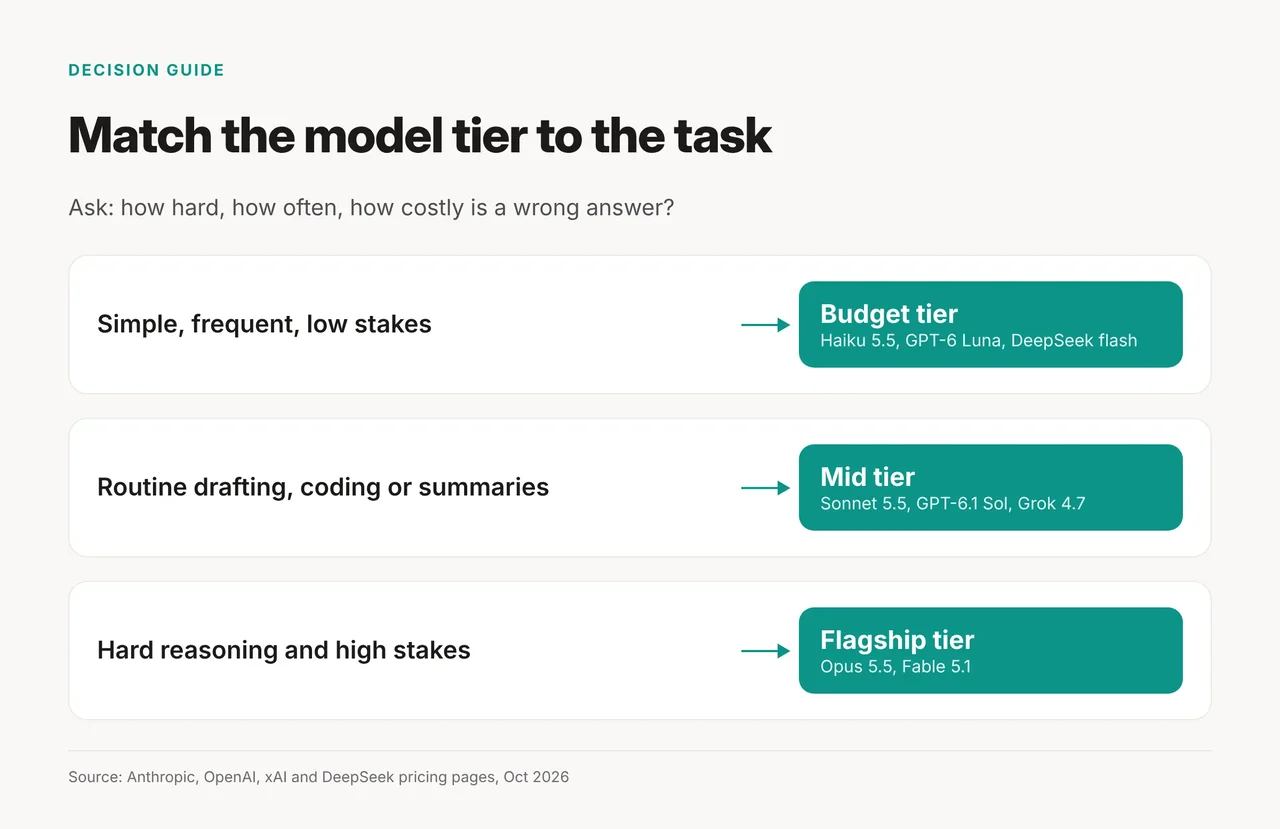
- Budget tier (Claude Haiku 5.5, GPT-6 Luna, DeepSeek flash): rewriting a paragraph, short factual answers, formatting text, and any small task you run hundreds of times a day.
- Mid tier (Claude Sonnet 5.5, GPT-6.1 Sol, Grok 4.7, Kimi K3): full email and document drafts, routine coding, and summaries of a single document. Grok 4.7 is xAI's flagship but is priced like a mid-tier model.
- Flagship tier (Claude Opus 5.5, Claude Fable 5.1, GPT-6 Astra): debugging across many files, work with financial, legal or safety weight, and tasks where a subtle error costs more than a slow answer.
Before you move routine coding between Claude tiers, read our Sonnet 5.5 vs Opus 5.5 routing guide.
What do the tiers cost today?
Prices below are per 1M tokens, standard API tier, checked on the vendors' pages on October 21, 2026.
| Model | Input | Output | Tier |
|---|---|---|---|
| Claude Haiku 5.5 | $0.10 | $0.50 | Budget |
| GPT-6 Luna | $0.10 | $0.50 | Budget |
| DeepSeek flash (off-peak) | $0.15 | $0.60 | Budget |
| Grok 4.7 | $2 | $6 | Mid |
| Claude Sonnet 5.5 | $2 | $10 | Mid |
| GPT-6.1 Sol | $2 | $10 | Mid |
| Kimi K3 | $3 | $15 | Mid |
| Claude Opus 5.5 | $4 | $20 | Flagship |
| Claude Fable 5.1 | $10 | $50 | Flagship |
| GPT-6 Astra | $10 | $50 | Flagship |
Read the fine print before you commit. Haiku 5.5's rate covers prompts up to 100,000 tokens and rises to $0.50 / $2.50 above that. DeepSeek charges double during weekday peak hours, so flash becomes $0.30 / $1.20. Still on GPT-5.6 Sol? Its promotional $4 / $20 rate runs at least through November 21, 2026, double GPT-6.1 Sol's $2 / $10.
The full spread is 100x: Fable 5.1 costs 100 times Luna on both input and output. Check Claude pricing and OpenAI API pricing again before you set a budget.
How do you route your tasks in five steps?
Run these five steps once for your team's recurring work. Each step ends with something you can check.
- List your recurring tasks. Write down each task your team runs through a model, with a rough monthly volume. You should end with one line per task.
- Answer the three questions for each task. Mark reasoning as simple or complex, volume as rare or frequent, and stakes as low or high. Each task now has a tentative tier.
- Test the cheaper tier on real inputs. Run a sample of last week's actual requests through the tier you picked. Keep it only if the answers pass the same review you use today.
- Price the workload. Multiply monthly input and output tokens by the per-1M prices above. Our guide to AI tokens explains how to estimate token counts.
- Set the default and log exceptions. Make the tested tier the default for that task. Note every time someone escalates to the flagship, and why.
Routing by hand works for a few tasks. At higher volume, an AI model router can apply the same rule automatically.
Does lowering reasoning effort beat switching models?
Sometimes it does, because you keep the same model and just change how much it thinks. Anthropic says its effort parameter lets you "control how many tokens Claude spends" with a single model.
OpenAI's reasoning.effort setting works the same way. Its supported values "are model-dependent," from none up to max. xAI lists reasoning as configurable for Grok 4.7, and DeepSeek flash has thinking and non-thinking modes.
Try a lower effort setting before you drop a tier. Output tokens cost the most on every model above, so shorter thinking cuts the bill directly.
Where this breaks, and when is the flagship worth it?
Routing fails in both directions, so watch for these four mistakes.
- Flagship by habit. Running simple, repeated tasks on Opus 5.5 as a safety net multiplies the bill 40x in the first scenario.
- Budget on high stakes. A cheap wrong answer on a contract or a production bug can cost more than months of token savings.
- Stale prices. Older lines such as Claude Opus 5 are now legacy and priced differently. Recheck your table each month.
- Skipping the test. Price says nothing about quality. Never switch a task without step 3.
The flagship is worth it when the reasoning is hard and the stakes are high. Multi-file debugging and work with legal or financial weight belong there, even at 40 times the price.
Quick questions
Should I use one model for everything? No. A single default overpays on simple work or underpowers hard work. Route each recurring task separately.
Is the cheapest model good enough for email? Test it on your own drafts first. In the second scenario, Haiku 5.5 would cost $5.70 a month against $114 for Sonnet 5.5.
Does lowering reasoning effort save money? Usually, because thinking produces output tokens and output costs more. Check your provider's effort settings first.
Make it a habit: a monthly routing checklist
Spend one short session a month on this list.
- Every recurring task has a named tier and a reason.
- You checked each vendor's pricing page this month.
- You tried a lower reasoning effort before any tier change.
- Every flagship escalation from last month has a logged reason.
- You know what each task costs per month; our AI agent cost guide shows the math.
The rule to keep: cheapest tier that passes your test, flagship only when stakes demand it.