The result: a chat model running on your own computer, set up in about 10 minutes. Start with Ollama if you can type one command, LM Studio if you'd rather click, and llama.cpp if you want every setting.
Before you download anything, check that the model fits your memory. The rule below tells you in one line.
Start with Ollama for one command, LM Studio for clicks, llama.cpp for control
Pick the tool by how you like to work, not by its feature list. All three run models on your own machine.
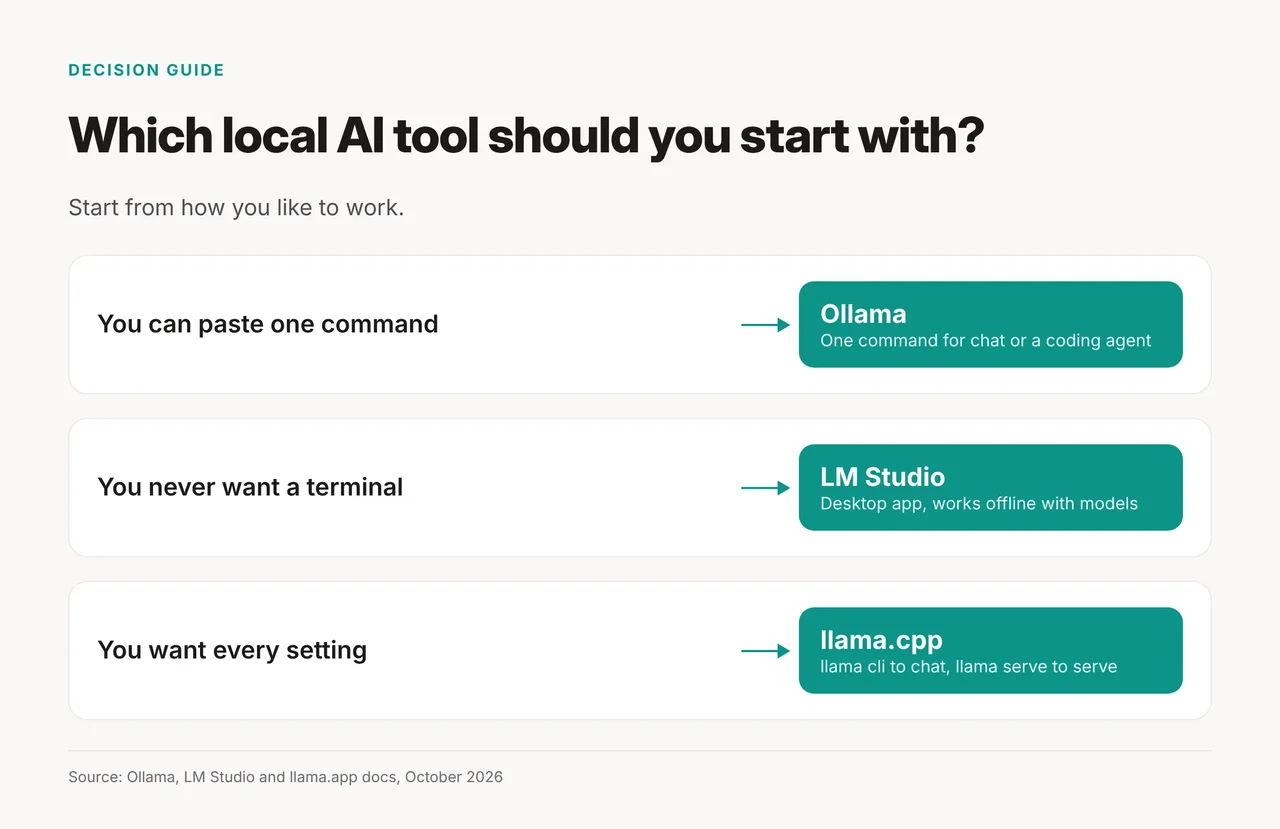
- Ollama suits you if you can paste one command. Since release v0.32.0, typing
ollamaon its own "launches an agent to help you code and delegate work." The latest release is v0.40.7, out October 18. - LM Studio suits you if you never want a terminal. The current Windows download is version 0.4.26. LM Studio says it "can operate entirely offline, just make sure to get some model files first." It can also "serve local models on OpenAI-like endpoints."
- llama.cpp suits you if you want control. The official llama.app installer gives you one
llamacommand withllama clifor chat andllama servefor a server.
One 2026 note: LM Studio also makes Bionic, an app that runs local models on the LM Studio runtime or cloud models. LM Studio says "Bionic is a new, separate app from LM Studio."
How much memory does a local model need?
Model size is roughly parameters x bits per weight / 8. Fewer bits per weight means a smaller file, and llama.cpp's docs warn that quantization "may introduce some accuracy loss."
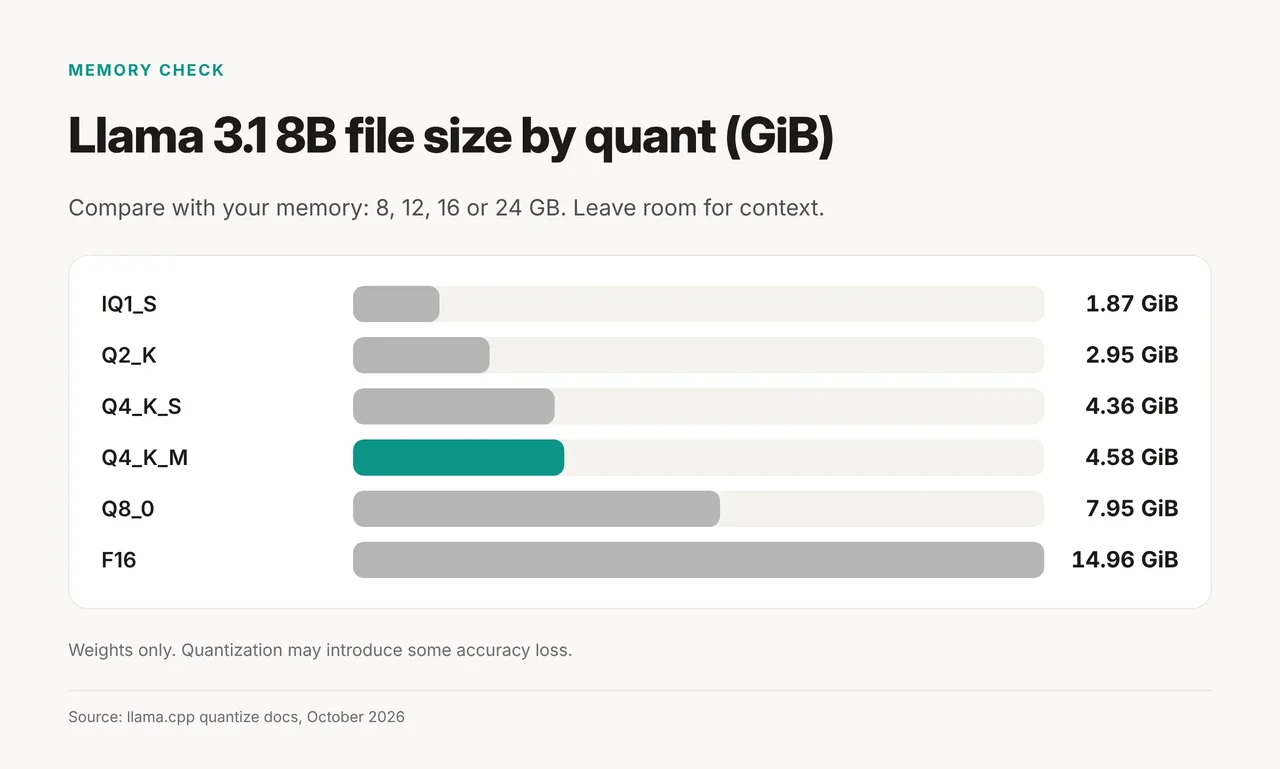
Here is llama.cpp's official table for the same 8B model:
| Quant | Bits per weight | File size (GiB) |
|---|---|---|
| IQ1_S | 2.00 | 1.87 |
| Q2_K | 3.16 | 2.95 |
| Q4_K_S | 4.67 | 4.36 |
| Q4_K_M | 4.89 | 4.58 |
| Q8_0 | 8.50 | 7.95 |
| F16 | 16.00 | 14.96 |
Q4_K_M is 3.3 times smaller than F16 for the same model. Run the rule the other way and 16 GB holds about 26B parameters at Q4_K_M, before context. A 70B model at Q4_K_M needs about 43 GB (40 GiB), more than most gaming cards have.
Ollama's Gemma 4 tags show the same idea with real downloads. Sizes are ranges because each tag has several variants:
| Your memory | Gemma 4 tag that fits | Download size |
|---|---|---|
| 8 GB | gemma4:e2b | 4.6GB-7.5GB |
| 16 GB | gemma4 (latest, e4b) | 6.6GB-9.5GB |
| 24 GB VRAM | gemma4:26b or gemma4:31b | 16GB-19GB or 19GB-20GB |
LM Studio recommends 16GB+ RAM on a Mac. On Windows it asks for at least 16GB of RAM and "at least 4GB of dedicated VRAM." Macs with 8GB "may work with smaller models and modest context sizes."
Why context silently eats memory
The context window is how much of the chat the model can see at once, and it needs memory on top of the model file. That's why LM Studio pairs small Macs with "modest context sizes."
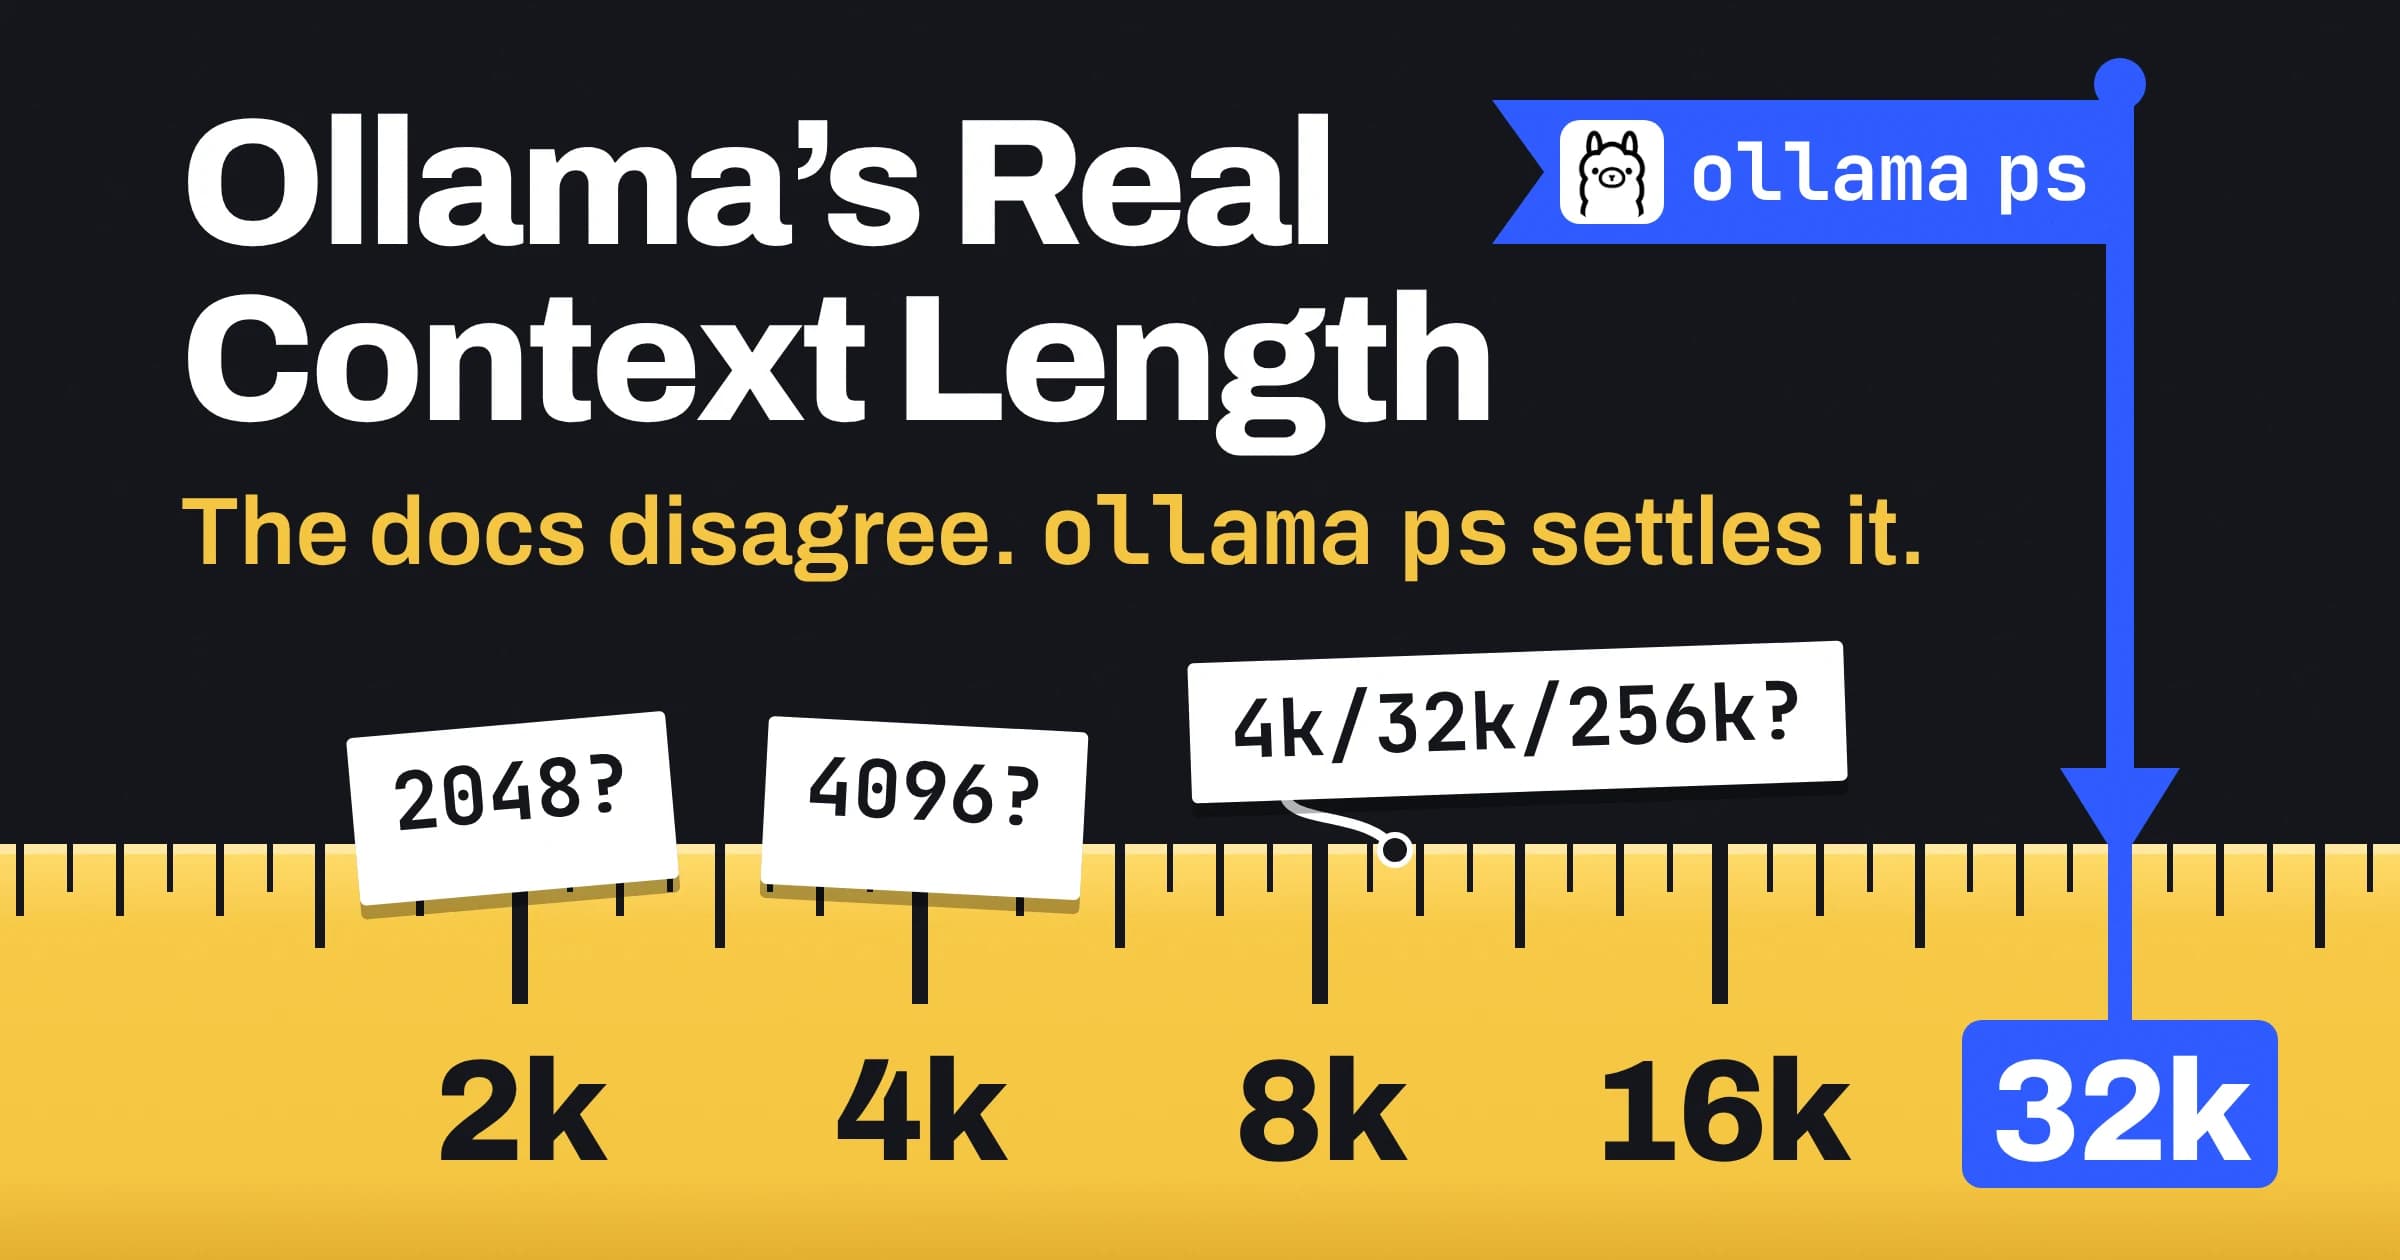
Ollama sets its default window from your graphics memory. Its docs list "< 24 GiB VRAM: 4k context", "24-48 GiB VRAM: 32k context" and ">= 48 GiB VRAM: 256k context." Most home GPUs sit in the first band, so long documents may not fit.
If you plan to use agents, Ollama says agent tasks "should be set to at least 64000 tokens." Budget memory for that before you pick a bigger model. For more on keeping prompts lean, see context engineering.
Run your first model in 10 minutes
The fastest path is Ollama's quickstart. Each step says what you should see.
- Install Ollama. On macOS or Linux, run
curl -fsSL https://ollama.com/install.sh | sh. On Windows, runirm https://ollama.com/install.ps1 | iexin PowerShell. Check: theollamacommand now works. - Open it. Run
ollamaand "Follow the setup prompts." Check: you're asked to "Sign in to use cloud models, or choose a local model." Pick a local one. - Download a small model. Run
ollama run gemma4:e2b. Check: the download starts. Gemma 4 E2B is about 7.2 GB. - Chat. Type a question and press Enter. Check: an answer appears. Ollama recommends 8 GB of available VRAM or unified memory. System RAM works but responses "may be slower."
- Leave. Type
/byeto leave. Check: you're back at the normal prompt.
Prefer clicks? Check LM Studio's system requirements first: macOS 14.0 or newer on Apple Silicon, an AVX2 x64 or Snapdragon X Elite PC, or Ubuntu 20.04 or newer. Want control? Run curl -LsSf https://llama.app/install.sh | sh to install llama.cpp. On Windows, run irm https://llama.app/install.ps1 | iex in PowerShell.
Where this breaks: five first-run mistakes
Most bad first runs come from one of these five.
- Picking a quant that doesn't fit. The same 8B model ranges from 1.87 GiB to 14.96 GiB. Check the table before you download.
- Expecting cloud quality from tiny quants. IQ1_S is 8 times smaller than F16, and quantization "may introduce some accuracy loss." Use the smallest quant only when nothing else fits.
- Forgetting context. Below 24 GiB of VRAM, Ollama's default is 4k. Long documents and agent work need more, and more needs memory.
- Running from system RAM. It works, but Ollama says responses "may be slower."
- Old NVIDIA drivers. Ollama "supports Nvidia GPUs with compute capability 5.0+ and driver version 550 and newer." Cards with compute capability 5.0 through 6.2 "require driver version 570 or newer."
Make it a habit: check before every new model
Run the same three checks each time you try a model:
- Size: parameters x bits / 8, or read the tag's download size. Leave headroom under your memory.
- Context: know your default window, and plan for 64000 tokens if you use agents.
- Version: update the app. Bionic, for example, needs LM Studio 0.4.26 or newer.
For choosing a model family, see picking the right AI model. On Macs, Ollama says MLX made Gemma 4 "up to 90% faster when used with coding agents," measured with the Aider polyglot benchmark (June 2026). Connecting local models to other tools? Read up on the MCP protocol.
Local AI FAQs
Can 16 GB run a local model?
Yes. An 8B model at Q4_K_M is 4.58 GiB, and the default gemma4 tag is 6.6GB-9.5GB. That leaves room for context.
Can I run a 70B model on a gaming PC?
Usually not on the GPU alone. At Q4_K_M a 70B model needs about 43 GB (40 GiB). Pick an 8B model, or a Gemma 4 tag that fits your memory.
Does local AI stay on my computer?
Local models run on your machine, and LM Studio "can operate entirely offline" once you have model files. Ollama also offers cloud models if you sign in, and LM Studio's separate Bionic app has cloud models too, so check which one you picked.